
Flapping Airplanes, a year-old AI lab working on training large models with less data, has raised a $1 billion Series A at a reported $6 billion valuation. The round was co-led by Index and Lux and arrived nine months after launch. The financing matters for business because it funds an alternative approach to model building focused on lower training and operating costs.
How the $1B round was put together
The Series A follows a $180 million seed round from GV, Sequoia and Index that had valued the company at $1.5 billion. The new valuation therefore represents a fourfold increase in under a year. Earlier backers Sequoia, GV and Kleiner Perkins joined the new round. Other investors named in the company include Valor, Atreides, A*, Kleiner Perkins and Nvidia. The fresh capital is earmarked for hiring and for turning the research goal into working systems.
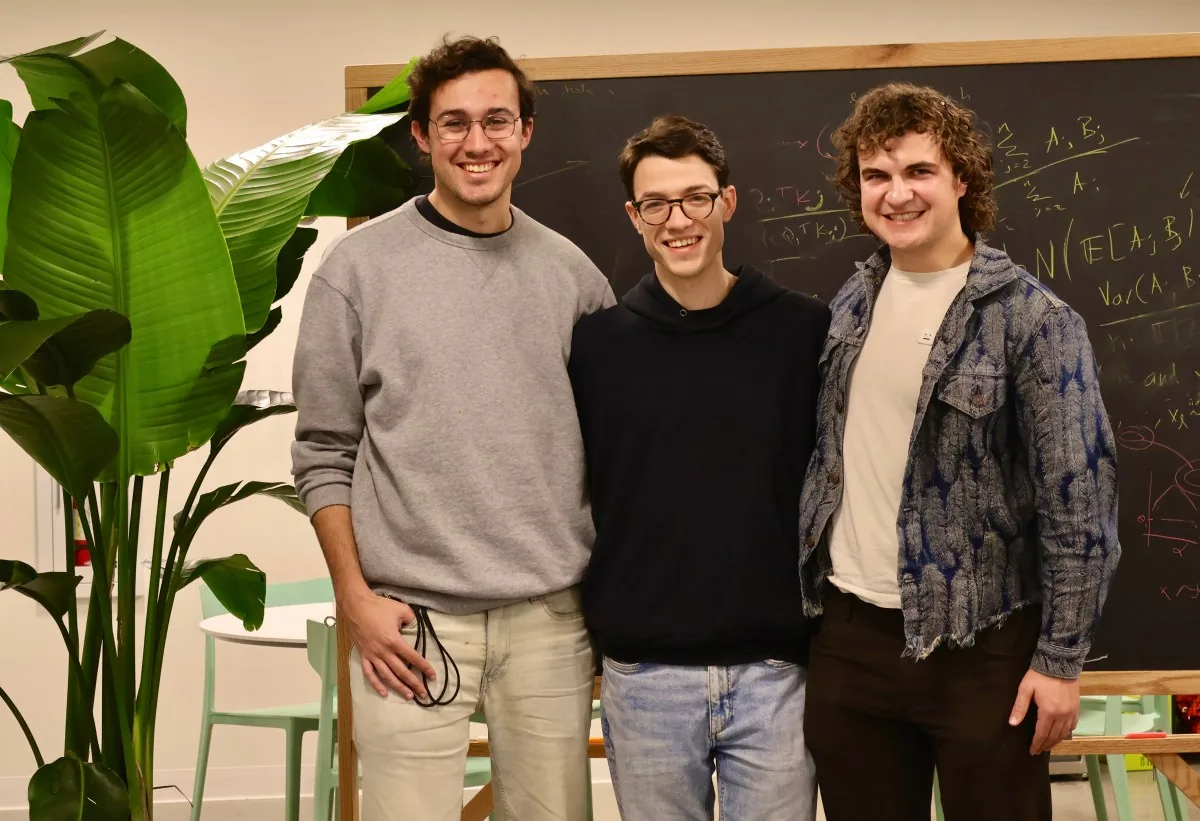
The company was founded by Aidan Smith and brothers Asher and Ben Spector. Smith is a former founder and Thiel fellow who worked at Neuralink during college. Asher Spector pursued a statistics PhD at Stanford, while Ben Spector pursued a computer science PhD at Stanford and founded Prod while at MIT. Prod is a five-year-old student-run startup accelerator described by Sequoia partner David Cahn as a talent incubator. Cahn, an investor in the company, called the team a young person’s AGI lab.
The founders describe their work as a complete megakernel framework. A kernel is a program that runs on a GPU, while a megakernel bundles many tasks into one program. Their system is said to perform training runs, serve inference, play video games, and even do all three at once inside a single kernel. The design overlaps memory-bound inference with compute-bound training. That pairing places a task waiting for data alongside a task performing calculations, which keeps the chip occupied instead of idle.
What cheaper training means for companies
For companies that buy or deploy AI, the practical interest lies in systems that cost less to train and run. If one framework can handle training and inference together, buyers could need fewer separate setups and make better use of existing GPU capacity. Small firms would feel the difference through lower entry costs for custom models. Large firms would feel it through reduced compute spending across many workloads and faster reuse of infrastructure.
The approach still needs verification in production conditions. The company has described architecture and intent, but customers lack public benchmarks, delivery dates, pricing terms and support conditions. The claim of models that avoid ingesting half the internet remains a research target rather than a product specification. Buyers should ask what data volumes are required, which GPUs are supported, how inference quality is measured, and what limitations apply to simultaneous workloads.
A marker to watch is hiring progress and the first externally tested release of the megakernel system. Asher Spector has linked data efficiency to economic use, saying a model a million times more data efficient is probably a million times easier to put into the economy. If the $1 billion allows the lab to demonstrate that efficiency on real tasks, enterprise demand for low-data training will gain a concrete supplier.
